AI for Education
 Active
PI: Nisansa de Silva
The AI for Education project explores how artificial intelligence and digital technologies can enhance teaching, learning, and educational management within the Sri Lankan context.

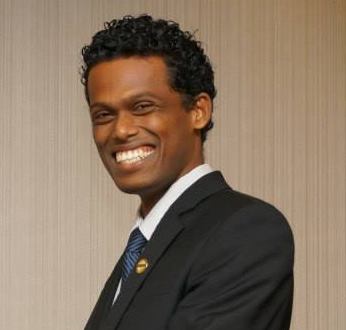
PhD (UO), MS (UO), Bsc Eng. (Hons) (Moratuwa)
Nisansa de Silva is a senior lecturer at the Department of Computer Science & Engineering, University of Moratuwa, Sri Lanka. He obtained his Ph.D (2020, advisor: Dejing Dou) and MS (2016) degrees in Computer and Information Science from University of Oregon, USA and his BSc (Hons) in Computer Science & Engineering (2011) degree from University of Moratuwa. He joined University of Moratuwa as a lecturer in 2011. From 2013 to 2014, he worked as a researcher at LIRNEasia. In 2018, he worked as a Givens Associate at Argonne National Laboratory, USA. Eng. Dr. de Silva has over 50 peer reviewed publications in the field of computer science, mostly under the subfields of Natural Language Processing and Artificial Intelligence, earning more than 800 citations. He is also an associate member of the IESL.
Keywords: Natural Language Processing | Machine Learning / Deep Learning | Ontologies | Big Data | Bioinformatics | Sinhala | Law | DnD | Education | Sentiment Analysis | Low-resource Languages | Information Extraction | LLM | Aspect-based Sentiment Analysis | Social Media | Information Retrieval | Word Embeddings | Data Science | Semantic Similarity | Legal Domain | Pre-trained Models | Corpus Linguistics | Named Entity Recognition | Text Generation | Legal Party Identification | Corpus | Classification | Software Evolution | Code Generation | Transfer Learning | Semantic Analysis | Coreference Resolution | Automated Program Repair | Embedding | Semantic Oppositeness | Translation | Sinhala Diachronic Corpus | Diachrony | Knowledge Graph | Language Change | Parallel Corpora | Word2vec | Aspect Extraction | Neural Networks | WordNet | Data Annotation | Word Embedding Alignment | Discourse Relations | Explainable Artificial Intelligence | Tamil | Text Classification | Technology in Education | Ontology Development | Public Policy | Text Summarization | Multi-document summarization | Multilingual | Emotion Recognition | Legal Information Extraction | Multilingual Embedding | Inflected Languages | Web-mined Parallel Corpora | Lexicon | Parallel Data Curation | Computer Science Education | Cultural Alignment | Data Mining | Common Sense Reasoning | Rule-based | Software Engineering Projects | Engineering Education | Crowdsourcing | Data Quality | Graph Embedding | Sentence Embedding | Representation | Low-resource Settings | Sequence-to-sequence Learning | Mobile App Review Analysis | Cross-lingual Representations | Bilingual Lexicon Induction | Aspect Sentiment Triple Extraction | Word Vectorization | Multi-agent |
Dissertations
Naida Hewa Nisansa Dilushan de Silva, "Semantic Oppositeness for Inconsistency and Disagreement Detection in Natural Language", University of Oregon, 2020
Book chapters
N. H. Nisansa D de Silva, "Relational Databases and Biomedical Big Data", Bioinformatics in MicroRNA Research, pp. 69--81, 2017. doi: 10.1007/978-1-4939-7046-9_5
Journal Papers
Krishan Chavinda, Pasan Kalansooriya, Thushalya Weerasuriya, Nisansa de Silva, Uthayasanker Thayasivam, Kogul Srikandabala, Kirishnni Prabagar, and Damminda Alahakoon, "An emotion aware context adaptive machine learning approach for detecting hate speech in social media", Neural Computing and Applications, vol. 38, no. 8, pp. 1433-3058, 2026. doi: 10.1007/s00521-026-12029-8
W M Yomal De Mel and Nisansa de Silva, "Linguistic Analysis of Sinhala YouTube Comments on Sinhala Music Videos: A Dataset Study", ICTer, vol. 18, no. 2, pp. 121-130, 2025. doi: 10.4038/icter.v18i2.7299
Dineth Jayakody, A V A Malkith, Koshila Isuranda, Vishal Thenuwara, Nisansa de Silva, Sachintha Rajith Ponnamperuma, G G N Sandamali, and K L K Sudheera, "Instruct-DeBERTa: A Hybrid Approach for Aspect-based Sentiment Analysis on Textual Reviews", ICTer, vol. 18, no. 2, pp. 39-50, 2025. doi: 10.4038/icter.v18i2.7290
Vihanga Jayawickrama, Gihan Weeraprameshwara, Nisansa de Silva, and Yudhanjaya Wijeratne, "Facebook for Sentiment Analysis: Baseline Models to Predict Facebook Reactions of Sinhala Posts", The International Journal on Advances in ICT for Emerging Regions, vol. 15, no. 2, 2022. doi: 10.4038/icter.v15i2.7248
Sahan Jayasinghe, Lakith Ransika Rambukkanage, Ashan Silva, Nisansa de Silva, and Amal Shehan Perera, "Unified Legal Party Based Sentiment Analysis Pipeline", The International Journal on Advances in ICT for Emerging Regions, vol. 15, no. 2, 2022. doi: 10.4038/icter.v15i2.7247
Gathika Ratnayaka, Nisansa de Silva, Amal Shehan Perera, Gayan Kavirathne, Thirasara Ariyarathna, and Anjana Wijesinghe, "Context Sensitive Verb Similarity Dataset for Legal Information Extraction", Data, vol. 7, no. 7, 2022. doi: 10.3390/data7070087
Chamodi Samarawickrama, Melonie de Almeida, Nisansa de Silva, Gathika Ratnayaka, and Amal Shehan Perera, "Legal Party Extraction from Legal Opinion Texts Using Recurrent Deep Neural Networks", Journal of Data Intelligence, vol. 3, no. 3, pp. 350--365, 2022. doi: 10.26421/JDI3.3-4
Isanka Rajapaksha, Chanika Ruchini Mudalige, Dilini Karunarathna, Nisansa de Silva, Gathika Ratnayaka, and Amal Shehan Perera, "Sigmalaw PBSA-A Deep Learning Approach for Aspect-Based Sentiment Analysis in Legal Opinion Texts", Journal of Data Intelligence, vol. 3, no. 1, pp. 101--115, 2021. doi: 10.26421/JDI3.1-1
Gathika Ratnayaka, Thejan Rupasinghe, Nisansa de Silva, Menuka Warushavithana, Viraj Gamage, Madhavi Perera, and Amal Shehan Perera, "Classifying Sentences in Court Case Transcripts using Discourse and Argumentative Properties", ICTer, vol. 12, no. 1, 2019. doi: 10.4038/icter.v12i1.7200
Pengwei Wang, Lei Ji, Jun Yan, Dejing Dou, Nisansa de Silva, Yong Zhang, and Lianwen Jin, "Concept and Attention-Based CNN for Question Retrieval in Multi-View Learning", ACM Transactions on Intelligent Systems and Technology (TIST), vol. 9, no. 4, pp. 41, 2018. doi: 10.1145/3151957
Vindula Jayawardana, Dimuthu Lakmal, Nisansa de Silva, Amal Shehan Perera, Keet Sugathadasa, Buddhi Ayesha, and Madhavi Perera, "Word Vector Embeddings and Domain Specific Semantic based Semi-Supervised Ontology Instance Population", International Journal on Advances in ICT for Emerging Regions, vol. 10, no. 1, pp. 1, 2017. doi: 10.4038/icter.v11i1.7191
Fernando Gutierrez, Dejing Dou, Nisansa de Silva, and Stephen Fickas, "Online Reasoning for Semantic Error Detection in Text", Journal on Data Semantics, 07. 2017. doi: 10.1007/s13740-017-0079-6
Jingshan Huang, Fernando Gutierrez, Harrison J Strachan, Dejing Dou, Weili Huang, Barry Smith, Judith A Blake, Karen Eilbeck, Darren A Natale, Yu Lin, Bin Wu, Nisansa de Silva, and others, "OmniSearch: a semantic search system based on the Ontology for MIcroRNA Target (OMIT) for microRNA-target gene interaction data", Journal of biomedical semantics, vol. 7, no. 1, pp. 25, 2016. doi: 10.1186/s13326-016-0064-2
Jingshan Huang, Karen Eilbeck, Barry Smith, Judith A Blake, Dejing Dou, Weili Huang, Darren A Natale, Alan Ruttenberg, Jun Huan, Michael T Zimmermann, Guoqian Jiang, Yu Lin, Bin Wu, Harrison J. Strachan, Nisansa de Silva, and others, "The development of non-coding RNA ontology", International journal of data mining and bioinformatics, vol. 15, no. 3, pp. 214--232, 2016. doi: 10.1504/IJDMB.2016.077072
Sriganesh Lokanathan, Gabriel E Kreindler, N. H. Nisana de Silva, Yuhei Miyauchi, Dedunu Dhananjaya, and Rohan Samarajiva, "The Potential of Mobile Network Big Data as a Tool in Colombo's Transportation and Urban Planning", Information Technologies \& International Development, vol. 12, no. 2, pp. pp--63, 2016
Eranga Mapa, Lasitha Wattaladeniya, Chiran Chathuranga, Samith Dassanayake, Nisansa de Silva, Upali Kohomban, and Danaja Maldeniya, "Text Normalization in Social Media by using Spell Correction and Dictionary Based Approach", Systems Learning, vol. 1, pp. 1--6, 2012
Conference Papers
Dhinanjaya Fernando, Dinura Ginige, Kalana Lakshan, Chanupa Gurusinghe, Lasana Pahanga, Subavarshana Arumugam, Sandeepa Weerasekara, Sandareka Wickramanayake, and Nisansa de Silva, "The Remittance Blueprint: Data-driven Intelligence for Sri Lanka", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 61-66. doi: 10.1109/MERCon71835.2026.11691526
Himath Dhanapala, Haren Daishika, Himandhi Kuruppu, Sithija Seneviratne, Ashini Kavindya, Patalee Narasinghe, Sandeepa Weerasekara, Nisansa de Silva, and Sandareka Wickramanayake, "Trilingual Topic Modeling of Sri Lankan Parliamentary Debates", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 389-394. doi: 10.1109/MERCon71835.2026.11691324
Tharusha Perera, Janith Mahanama, Maleesha Kumarasinghe, Bimsara Udurawana, Praveen Nawarathna, Patalee Narasinghe, Nathali Athukorala, Sandareka Wickramanayake, and Nisansa de Silva, "The Effect of Search Intent Data on Predicting Post-Crisis Daily Tourist Arrivals in Sri Lanka", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 395-400. doi: 10.1109/MERCon71835.2026.11691456
Ruzaini Ahmedh, Yohan Jayasinghe, Tharumini Gamage, Ifaz Ikram, Hasini Lawanya, Nirasha Munasinghe, Patalee Narasinghe, Nisansa de Silva, and Sandareka Wickramanayake, "Monsoon Mayhem to Market Waves: Forecasting Fisheries Resilience in Sri Lanka", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 401-406. doi: 10.1109/MERCon71835.2026.11691272
Anupama Wickramaratne, Thevindu Fernando, Tharupahan Jayawardana, Dehan Wijesinghe, Senindu Dinapura, Madara Mendis, Nevidu Jayatilleke, Nisansa de Silva, and Sandareka Wickramanayake, "Impact of Cyclone Ditwah on the Colombo Stock Exchange: An Event Study on Market Reactions to Natural Disasters", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 407-412. doi: 10.1109/MERCon71835.2026.11691317
Rahim Iqbal, Asfi Ahamed, Izzath Nisfer, Shazan Shaheed, Muhammadu Ilham, Nathali Athukorala, Madara Mendis, Nisansa de Silva, and Sandareka Wickramanayake, "Environmental Drivers of Respiratory Disease: A District Level Analysis", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 413-418. doi: 10.1109/MERCon71835.2026.11691342
Ranuga Weerasekara, Heshan Nethmina, Manuja Ranathunga, Vinma Wettasinghe, Dinithi Navodya, Subavarshana Arumugam, Nirasha Munasinghe, Nisansa de Silva, and Sandareka Wickramanayake, "When Prices Double in a Week: Forecasting of Agricultural Volatility in Import-Isolated Markets", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 419-424. doi: 10.1109/MERCon71835.2026.11691365 
Sonath Kirindage, Vihanga Nimsara, Sakindu Rajapaksa, Kavyanga Hathurusinghe, Lahiru Dilshan, Subavarshana Arumugam, Nathali Athukorala, Sandareka Wickramanayake, and Nisansa de Silva, "Golden Hour Divide: Trauma Care Accessibility and Resource Vulnerability in Sri Lanka", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 425-430. doi: 10.1109/MERCon71835.2026.11691402
Hesandi Mallawarachchi, Senilka Madurapperumage, Nadil Kulathunge, Thilokya Angeesa, Nethsith Gunaweera, Sandeepa Weerasekara, Patalee Narasinghe, Nisansa de Silva, and Sandareka Wickramanayake, "Forecasting Weather-Driven Price Dynamics Across Sri Lankan Tea Market Catalogues", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 431-436. doi: 10.1109/MERCon71835.2026.11691572
Dilusha Chandrasiri, Maneesha Herath, Yasith Hewarathna, Muditha Herath, Gishan Bandara, Madara Mendis, Nathali Athukorala, Nisansa de Silva, and Sandareka Wickramanayake, "How Environment and Urbanization Shape Bird Diversity in Sri Lanka", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 437-442. doi: 10.1109/MERCon71835.2026.11691486
Ramanaish Abaiyan, Ruththiragayan Sutharsan, Kusal Amantha, Anusan Krishnathas, Asma Rauff, Kovindarajah Sriyathurshan, Patalee Narasinghe, Nirasha Munasinghe, Nisansa de Silva, and Sandareka Wickramanayake, "Fault of Our Stars: Behavioral Drivers of Rating-Sentiment Incongruence", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 443-448. doi: 10.1109/MERCon71835.2026.11691426
Lakshani Galwatta, Nisansa de Silva, Sarangi Aththanayake, and Adithya Galwatta, "SalAngaBhava: A Sinhala Market Dataset for Aspect-based Sentiment Analysis", in 2026 Moratuwa Engineering Research Conference (MERCon), 2026, pp. 664-669. doi: 10.1109/MERCon71835.2026.11691353
Tharani Jayaratne and Nisansa de Silva, "Hybrid Genealogical Relationship Extraction from Wikipedia", in Applied Data Science \& Artificial Intelligence Conference, 2026.
Kaushal Kahapola, Sharada Galappaththi, Dinith Ranasinghe, Ridwan Shariffdeen, Nisansa de Silva, Srinath Perera, and Sandareka Wickramanayake, "JavaBackports: A Dataset for Benchmarking Automated Backporting in Java", in 23rd International Conference on Mining Software Repositories (MSR), 2026, pp. 712-716. doi: 10.1145/3793302.3793331
Mineth Weerasinghe, Himindu Kularathne, Methmini Madhushika, Danuka Lakshan, Nisansa de Silva, Adeesha Wijayasiri, and Srinath Perera, "From Monolith to Microservices: A Comparative Evaluation of Decomposition Frameworks", in Recent Trends and Challenges in Information Systems and Technologies, 2026, pp. 309--320. doi: 10.1007/978-3-032-32032-2_29
Rajith Arulanandam and Nisansa De Silva, "Section-Weighted Hybrid Approach for Legal Case Retrieval", in 2026 8th International Conference on Natural Language Processing (ICNLP), 2026, pp. 567--571. doi: 10.1109/ICNLP69856.2026.11527762
Nevidu Jayatilleke, Nisansa de Silva, Uthpala Nimanthi, Gagani Kulathilaka, Azra Safrullah, and Johan Sofalas, "SiDiaC-v. 2.0: Sinhala Diachronic Corpus Version 2.0", in Proceedings of the Fifteenth Language Resources and Evaluation Conference (LREC 2026), Palma, Mallorca, Spain: European Language Resources Association (ELRA), 05. 2026, pp. 6740--6763. doi: 10.63317/2ybff4o55vrq
K M Hewapathirana, Nisansa de Silva, and C D Athuraliya, "Adapter-Based Multi-Document Summarisation: Opinion Summarisation Use Case", in Proceedings of the 18th International Conference on Agents and Artificial Intelligence - Volume 4: ICAART, SciTePress, 2026, pp. 3018-3027. doi: 10.5220/0014349400004052 
Kavindu Warnakulasuriya, Prabhash Dissanayake, Navindu De Silva, Stephen Cranefield, Bastin Tony Roy Savarimuthu, Surangika Ranathunga, and Nisansa de Silva, "Evolution of Cooperation in LLM-Agent Societies: A Preliminary Study Using Different Punishment Strategies", in Coordination, Organizations, Institutions, Norms, and Ethics for Governance of Multi-Agent Systems XVIII, Springer Nature Switzerland, 2026, pp. 115--133. doi: 10.1007/978-3-032-17542-7_7
Akesh Gunathilake, Nadil Karunarathne, Tharusha Bandaranayake, Nisansa de Silva, and Surangika Ranathunga, "LMSpell: Neural Spell Checking for Low-Resource Languages", in 2026 Moratuwa Engineering Research Conference (MERCon), 2025, pp. 503-508. doi: 10.1109/MERCon71835.2026.11691371
Nevidu Jayatilleke and Nisansa de Silva, "SiDiaC: Sinhala Diachronic Corpus", in Proceedings of the 39th Pacific Asia Conference on Language, Information and Computation, 2025, pp. 511--527.
Aravinth Sivaganeshan, Nisansa de Silva, and Akila Peiris, "Fine-tuning an LLM to Generate Lore Coherent Encounters for Dungeons and Dragons", in Proceedings of the 39th Pacific Asia Conference on Language, Information and Computation, 2025, pp. 710--722.
K M Hewapathirana, Nisansa de Silva, C D Athuraliya, and Piumi Kandanaarachchi, "Domain Adaptation for Multi-document Summarisation: A Case Study in the Medical Research Domain", in Proceedings of the 39th Pacific Asia Conference on Language, Information and Computation, 2025, pp. 791--802.
Oshadha Wijerathne, Amandi Nimasha, Dushan Fernando, Nisansa de Silva, and Srinath Perera, "ScheduleMe: Multi-Agent Calendar Assistant", in Proceedings of the 39th Pacific Asia Conference on Language, Information and Computation, 2025, pp. 309--319.
Nevidu Jayatilleke and Nisansa de Silva, "Zero-shot OCR Accuracy of Low-Resourced Languages: A Comparative Analysis on Sinhala and Tamil", in Proceedings of the 15th International Conference on Recent Advances in Natural Language Processing-Natural Language Processing in the Generative AI Era, 2025, pp. 471--480.
Yomal De Mel and Nisansa de Silva, "GeeSanBhava: Sentiment Tagged Sinhala Music Video Comment Data Set", in International Conference on Computational Collective Intelligence, 2025, pp. 157--171. doi: 10.1007/978-3-032-10209-6_11
Vishal Thenuwara and Nisansa de Silva, "DESS: DeBERTa Enhanced Syntactic-Semantic Aspect Sentiment Triplet Extraction", in International Conference on Computational Collective Intelligence, 2025, pp. 185--199. doi: 10.1007/978-3-032-09318-9_13
Kasun Wickramasinghe and Nisansa de Silva, "How Good is BLI as an Alignment Measure: A Study in Word Embedding Paradigm", in International Conference on Computational Collective Intelligence, 2025, pp. 383--397. doi: 10.1007/978-3-032-10202-7_26
Imalsha Puranegedara, Themira Chathumina, Nisal Ranathunga, Nisansa de Silva, Surangika Ranathunga, and Mokanarangan Thayaparan, "Utilizing Multilingual Encoders to Improve Large Language Models for Low-Resource Languages", in Moratuwa Engineering Research Conference (MERCon), 2025. doi: 10.1109/MERCon67903.2025.11216992
H W K Aravinda, Rashad Sirajudeen, Samith Karunathilake, Nisansa de Silva, Surangika Ranathunga, and Rishemjit Kaur, "SinLlama-A Large Language Model for Sinhala", in Moratuwa Engineering Research Conference (MERCon), 2025. doi: 10.1109/MERCon67903.2025.11217094
Aloka Fernando, Nisansa de Silva, Menan Velayuthan, Charitha Rathnayaka, and Surangika Ranathunga, "Improving the quality of Web-mined Parallel Corpora of Low-Resource Languages using Debiasing Heuristics", in Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing, 2025, pp. 28252--28269. doi: 10.18653/v1/2025.emnlp-main.1435
B Karunarathne, V Nanayakkara, N de Silva, and T Ambegoda, "Equipping School Teachers with Technology: A Qualitative Study Based on a Training Program Conducted for School Teachers on Technology for Education", in EDULEARN25 Proceedings, 2025, pp. 9925--9931. doi: 10.21125/edulearn.2025.2580
Sadeep Gunathilaka and Nisansa de Silva, "Automatic Analysis of App Reviews Using LLMs", in Proceedings of the Conference on Agents and Artificial Intelligence, 2025, pp. 828-839. doi: 10.5220/0013375600003890
Yomal De Mel, Kasun Wickramasinghe, Nisansa de Silva, and Surangika Ranathunga, "Sinhala Transliteration: A Comparative Analysis Between Rule-based and Seq2Seq Approaches", in Proceedings of the First Workshop on Natural Language Processing for Indo-Aryan and Dravidian Languages, 2025, pp. 166--173.
Dineth Jayakody, Koshila Isuranda, A V A Malkith, Nisansa de Silva, Sachintha Rajith Ponnamperuma, G G N Sandamali, K L K Sudheera, and Kashnika Gimhani Sarathchandra, "Enhanced Aspect-Based Sentiment Analysis with Integrated Category Extraction for Instruct-DeBERTa", in Proceedings of the 38th Pacific Asia Conference on Language, Information and Computation, 2024, pp. 665--674.
Dineth Jayakody, Koshila Isuranda, A V A Malkith, Nisansa de Silva, Sachintha Rajith Ponnamperuma, G G N Sandamali, and K L K Sudheera, "Aspect-Based Sentiment Analysis Techniques: A Comparative Study", in 2024 Moratuwa Engineering Research Conference (MERCon), 2024, pp. 205--210. doi: 10.1109/MERCon63886.2024.10688631
Kushan Hewapathirana, Nisansa de Silva, and C D Athuraliya, "M2DS: Multilingual Dataset for Multi-document Summarisation", in International Conference on Computational Collective Intelligence, 2024, pp. 219--231. doi: 10.1007/978-3-031-70248-8_17
Dushan Kumarasinghe and Nisansa de Silva, "Abstract Generation with Hybrid Model Supported by Relevance Matrix", in International Conference on Computational Collective Intelligence, 2024, pp. 211--223. doi: 10.1007/978-3-031-70816-9_17
Surangika Ranathunga, Nisansa de Silva, Dilith Jayakody, and Aloka Fernando, "Shoulders of Giants: A Look at the Degree and Utility of Openness in NLP Research", in Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics, 2024.
Surangika Ranathunga, Nisansa de Silva, Menan Velayuthan, Aloka Fernando, and Charitha Rathnayake, "Quality Does Matter: A Detailed Look at the Quality and Utility of Web-Mined Parallel Corpora", in Proceedings of the 18th Conference of the European Chapter of the Association for Computational Linguistics (Volume 1: Long Papers), St. Julian{'}s, Malta: Association for Computational Linguistics, 03. 2024, pp. 860--880.
Gayashan Weerasundara and Nisansa de Silva, "A Multi-Stage Approach to Image Consistency in Zero-Shot Character Art Generation for the D\&D Domain", in Proceedings of the 16th International Conference on Agents and Artificial Intelligence - Volume 3: ICAART, SciTePress, 2024, pp. 235-242. doi: 10.5220/0012317600003636
Kasun Wickramasinghe and Nisansa de Silva, "Sinhala-English Word Embedding Alignment: Introducing Datasets and Benchmark for a Low Resource Language", in Proceedings of the 37th Pacific Asia Conference on Language, Information and Computation, 2023, pp. 424--435.
Gayashan Weerasundara and Nisansa de Silva, "Comparative Analysis of Named Entity Recognition in the Dungeons and Dragons Domain", in Proceedings of the 14th International Conference on Recent Advances in Natural Language Processing, 2023, pp. 1225--1233.
Aravinth Sivaganeshan and Nisansa De Silva, "Fine Tuning Named Entity Extraction Models for the Fantasy Domain", in 2023 Moratuwa Engineering Research Conference (MERCon), 2023, pp. 346--351. doi: 10.1109/MERCon60487.2023.10355501
Akila Peiris and Nisansa de Silva, "SHADE: Semantic Hypernym Annotator for Domain-Specific Entities-Dungeons and Dragons Domain Use Case", in 2023 IEEE 17th International Conference on Industrial and Information Systems (ICIIS), 2023, pp. 1--6. doi: 10.1109/ICIIS58898.2023.10253606
Kushan Hewapathirana, Nisansa de Silva, and C D Athuraliya, "Multi-Document Summarization: A Comparative Evaluation", in 2023 IEEE 17th International Conference on Industrial and Information Systems (ICIIS), 2023, pp. 19--24. doi: 10.1109/ICIIS58898.2023.10253581
Kasun Wickramasinghe and Nisansa de Silva, "Sinhala-English Parallel Word Dictionary Dataset", in 2023 IEEE 17th International Conference on Industrial and Information Systems (ICIIS), 2023, pp. 61--66. doi: 10.1109/ICIIS58898.2023.10253560
Sahan Jayasinghe, Lakith Rambukkanage, Ashan Silva, Nisansa de Silva, Shehan Perera, and Madhavi Perera, "Learning Sentence Embeddings in the Legal Domain with Low Resource Settings", in Proceedings of the 36th Pacific Asia Conference on Language, Information and Computation, 2022, pp. 494--502.
Gihan Weeraprameshwara, Vihanga Jayawickrama, Nisansa de Silva, and Yudhanjaya Wijeratne, "Sinhala Sentence Embedding: A Two-Tiered Structure for Low-Resource Languages", in Proceedings of the 36th Pacific Asia Conference on Language, Information and Computation, 2022, pp. 325--336. doi: 10.48550/ARXIV.2210.14472
Akila Peiris and Nisansa de Silva, "Synthesis and Evaluation of a Domain-specific Large Data Set for Dungeons \& Dragons", in Proceedings of the 36th Pacific Asia Conference on Language, Information and Computation, 2022, pp. 415--424.
Sadeep Gunathilaka and Nisansa De Silva, "Aspect-based Sentiment Analysis on Mobile Application Reviews", in 2022 22nd International Conference on Advances in ICT for Emerging Regions (ICTer), 2022, pp. 183--188. doi: 10.1109/ICTer58063.2022.10024070
Dushan Kumarasinghe and Nisansa de Silva, "Automatic Generation of Abstracts for Research Papers", in Proceedings of the 34th Conference on Computational Linguistics and Speech Processing (ROCLING 2022), 2022, pp. 221--229.
Sahan Jayasinghe, Lakith Rambukkanage, Ashan Silva, Nisansa de Silva, and Amal Shehan Perera, "Legal Case Winning Party Prediction With Domain Specific Auxiliary Models", in Proceedings of the 34th Conference on Computational Linguistics and Speech Processing (ROCLING 2022), 2022, pp. 205--213.
Surangika Ranathunga and Nisansa de Silva, "Some Languages are More Equal than Others: Probing Deeper into the Linguistic Disparity in the NLP World", in Proceedings of the 2nd Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics and the 12th International Joint Conference on Natural Language Processing, 2022, pp. 823--848. doi: 10.48550/ARXIV.2210.08523
Nisansa de Silva, "Selecting Optimum Seed Words for Wordle using Character Statistics", in 2022 Moratuwa Engineering Research Conference (MERCon), 2022, pp. 1--6. doi: 10.1109/MERCon55799.2022.9906176
Gihan Weeraprameshwara, Vihanga Jayawickrama, Nisansa de Silva, and Yudhanjaya Wijeratne, "Sentiment Analysis with Deep Learning Models: A Comparative Study on a Decade of Sinhala Language Facebook Data", in 2022 The 3rd International Conference on Artificial Intelligence in Electronics Engineering, Association for Computing Machinery, 2022, pp. 16-22. doi: 10.1145/3512826.3512829
Vihanga Jayawickrama, Gihan Weeraprameshwara, Nisansa de Silva, and Yudhanjaya Wijeratne, "Seeking Sinhala Sentiment: Predicting Facebook Reactions of Sinhala Posts", in 2021 21st International Conference on Advances in ICT for Emerging Regions (ICter), 2021, pp. 177-182. doi: 10.1109/ICter53630.2021.9774796
Sahan Jayasinghe, Lakith Rambukkanage, Ashan Silva, Nisansa de Silva, and Amal Shehan Perera, "Party-based Sentiment Analysis Pipeline for the Legal Domain", in 2021 21st International Conference on Advances in ICT for Emerging Regions (ICter), 2021, pp. 171-176. doi: 10.1109/ICter53630.2021.9774821
Sahan Jayasinghe, Lakith Rambukkanage, Ashan Silva, Nisansa de Silva, and Amal Shehan Perera, "Critical Sentence Identification in Legal Cases Using Multi-Class Classification", in 2021 IEEE 16th International Conference on Industrial and Information Systems (ICIIS), 2021, pp. 146--151. doi: 10.1109/ICIIS53135.2021.9660657
Melonie de Almeida, Chamodi Samarawickrama, Nisansa de Silva, Gathika Ratnayaka, and Shehan Perera, "Identifying Legal Party Members from Legal Opinion Documents using Natural Language Processing", in The 23rd International Conference on Information Integration and Web Intelligence, 2021, pp. 259--266. doi: 10.1145/3487664.3487700
Isanka Rajapaksha, Chanika Ruchini Mudalige, Dilini Karunarathna, Nisansa de Silva, Amal Shehan Perera, and Gathika Ratnayaka, "Sigmalaw PBSA-A Deep Learning Model for Aspect-Based Sentiment Analysis for the Legal Domain", in International Conference on Database and Expert Systems Applications, 2021, pp. 125--137. doi: 10.1007/978-3-030-86472-9_12
Nisansa de Silva and Dejing Dou, "Semantic Oppositeness Assisted Deep Contextual Modeling for Automatic Rumor Detection in Social Networks", in Proceedings of the 16th Conference of the European Chapter of the Association for Computational Linguistics: Main Volume, 2021, pp. 405--415. doi: 10.18653/v1/2021.eacl-main.31
Chamodi Samarawickrama, Melonie de Almeida, Nisansa de Silva, Gathika Ratnayaka, and Amal Shehan Perera, "Party Identification of Legal Documents using Co-reference Resolution and Named Entity Recognition", in 2020 IEEE 15th International Conference on Industrial and Information Systems (ICIIS), 2020, pp. 494--499. doi: 10.1109/ICIIS51140.2020.9342720
Isanka Rajapaksha, Chanika Ruchini Mudalige, Dilini Karunarathna, Nisansa de Silva, Gathika Rathnayaka, and Amal Shehan Perera, "Rule-Based Approach for Party-Based Sentiment Analysis in Legal Opinion Texts", in 2020 20th International Conference on Advances in ICT for Emerging Regions (ICTer), 2020, pp. 284--285. doi: 10.1109/ICTer51097.2020.9325435
Melonie de Almeida, Chamodi Samarawickrama, Nisansa de Silva, Gathika Ratnayaka, and Amal Shehan Perera, "Legal Party Extraction from Legal Opinion Text with Sequence to Sequence Learning", in 2020 20th International Conference on Advances in ICT for Emerging Regions (ICTer), 2020, pp. 143--148. doi: 10.1109/ICTer51097.2020.9325488
Qiuhao Lu, Nisansa de Silva, Dejing Dou, Thien Huu Nguyen, Prithviraj Sen, Berthold Reinwald, and Yunyao Li, "Exploiting Node Content for Multiview Graph Convolutional Network and Adversarial Regularization", in Proceedings of the 28th International Conference on Computational Linguistics, 2020, pp. 545--555. doi: 10.18653/v1/2020.coling-main.47
Chanika Ruchini Mudalige, Dilini Karunarathna, Isanka Rajapaksha, Nisansa de Silva, Gathika Ratnayaka, Amal Shehan Perera, and Ramesh Pathirana, "SigmaLaw-ABSA: Dataset for Aspect-Based Sentiment Analysis in Legal Opinion Texts", in 2020 IEEE 15th International Conference on Industrial and Information Systems (ICIIS), 2020, pp. 488--493. doi: 10.1109/ICIIS51140.2020.9342650
Gathika Ratnayaka, Nisansa de Silva, Amal Shehan Perera, and Ramesh Pathirana, "Effective Approach to Develop a Sentiment Annotator For Legal Domain in a Low Resource Setting", in Proceedings of the 34th Pacific Asia Conference on Language, Information and Computation, 2020, pp. 252--260.
Nisansa de Silva and Dejing Dou, "Semantic Oppositeness Embedding Using an Autoencoder-based Learning Model", in Database and Expert Systems Applications, 2019, pp. 159--174. doi: 10.1007/978-3-030-27615-7_12
Gathika Ratnayaka, Thejan Rupasinghe, Nisansa de Silva, Menuka Warushavithana, Viraj Gamage, and Amal Shehan Perera, "Identifying Relationships Among Sentences in Court Case Transcripts Using Discourse Relations", in 2018 18th International Conference on Advances in ICT for Emerging Regions (ICTer), 2018, pp. 13--20. doi: 10.1109/ICTER.2018.8615485
Keet Sugathadasa, Buddhi Ayesha, Nisansa de Silva, Amal Shehan Perera, Vindula Jayawardana, Dimuthu Lakmal, and Madhavi Perera, "Legal Document Retrieval using Document Vector Embeddings and Deep Learning", in Science and information conference, 2018, pp. 160--175. doi: 10.1007/978-3-030-01177-2_12
Keet Sugathadasa, Buddhi Ayesha, Nisansa de Silva, Amal Shehan Perera, Vindula Jayawardana, Dimuthu Lakmal, and Madhavi Perera, "Synergistic Union of Word2Vec and Lexicon for Domain Specific Semantic Similarity", in 2017 IEEE International Conference on Industrial and Information Systems (ICIIS), 2017, pp. 1--6. doi: 10.1109/ICIINFS.2017.8300343
Vindula Jayawardana, Dimuthu Lakmal, Nisansa de Silva, Amal Shehan Perera, Keet Sugathadasa, Buddhi Ayesha, and Madhavi Perera, "Semi-Supervised Instance Population of an Ontology using Word Vector Embedding", in 2017 Seventeenth International Conference on Advances in ICT for Emerging Regions (ICTer), 2017, pp. 1--7. doi: 10.1109/icter.2017.8257822
Nisansa de Silva, Dejing Dou, and Jingshan Huang, "Discovering Inconsistencies in PubMed Abstracts Through Ontology-Based Information Extraction", in Proceedings of the 8th ACM International Conference on Bioinformatics, Computational Biology, and Health Informatics, New York, NY, USA: ACM, 2017, pp. 362--371. doi: 10.1145/3107411.3107452
Vindula Jayawardana, Dimuthu Lakmal, Nisansa de Silva, Amal Shehan Perera, Keet Sugathadasa, and Buddhi Ayesha, "Deriving a Representative Vector for Ontology Classes with Instance Word Vector Embeddings", in 2017 Seventh International Conference on Innovative Computing Technology (INTECH), 2017, pp. 79--84. doi: 10.1109/intech.2017.8102426
N. H. N. D. de Silva, "SAFS3 Algorithm: Frequency Statistic and Semantic Similarity Based Semantic Classification Use Case", in Advances in ICT for Emerging Regions (ICTer), 2015 Fifteenth International Conference on, 08. 2015, pp. 77--83. doi: 10.1109/ICTER.2015.7377670
Dimuthu Upeksha, Chamila Wijayarathna, Maduranga Siriwardena, Lahiru Lasandun, Chinthana Wimalasuriya, N. H. N. D. de Silva, and Gihan Dias, "Comparison Between Performance of Various Database Systems for Implementing a Language Corpus", in International Conference: Beyond Databases, Architectures and Structures, 05. 2015, pp. 82--91. doi: 10.1007/978-3-319-18422-7_7
Dimuthu Upeksha, Chamila Wijayarathna, Maduranga Siriwardena, Lahiru Lasandun, Chinthana Wimalasuriya, N. H. N. D. De Silva, and Gihan Dias, "Implementing a Corpus for Sinhala Language", in Symposium on Language Technology for South Asia 2015, 2015. doi: 10.13140/RG.2.2.23035.11047
U. L. D. N. Gunasinghe, W. A. M. De Silva, N. H. N. D. de Silva, A. S. Perera, W. A. D. Sashika, and W. D. T. P. Premasiri, "Sentence Similarity Measuring by Vector Space Model", in Advances in ICT for Emerging Regions (ICTer), 2014 International Conference on, 12. 2014, pp. 185--189. doi: 10.1109/ICTER.2014.7083899
Sachintha Rajith Ponnamperuma, Andun S. L. Gunawardana, Thilini Shanika, Prabahth Suminda Pathirana, Shahani Markus, and N. H. Nisansa Dilushan de Silva, "Novel Approach for Perception Analysis In a Learning Environment", in Teaching, Assessment and Learning (TALE), 2014 International Conference on, 12. 2014, pp. 148--154. doi: 10.1109/TALE.2014.7062607
S Lokanathan, N de Silva, G Kreindler, Y Miyauchi, and D Dhananjaya, "Using Mobile Network Big Data for Informing Transportation and Urban Planning in Colombo", Available at SSRN, 11. 2014
Indeewari Wijesiri, Malaka Gallage, Buddhika Gunathilaka, Madhuranga Lakjeewa, Daya Wimalasuriya, Gihan Dias, Rohini Paranavithana, and Nisansa de Silva, "Building a WordNet for Sinhala", in Proceedings of the Seventh Global WordNet Conference, 01. 2014, pp. 100--108.
N. H. N. D. de Silva, A. S. Perera, and M. K. D. T. Maldeniya, "Semi-Supervised Algorithm for Concept Ontology Based Word Set Expansion", in Advances in ICT for Emerging Regions (ICTer), 2013 International Conference on, 12. 2013, pp. 125--131. doi: 10.1109/ICTer.2013.6761166
E. L. Karannagoda, H. M. T. C. Herath, K. N. J. Fernando, M. W. I. D. Karunarathne, N. H. N. D. de Silva, and A. S. Perera, "Document Analysis Based Automatic Concept Map Generation for Enterprises", in Advances in ICT for Emerging Regions (ICTer), 2013 International Conference on, 12. 2013, pp. 154--159. doi: 10.1109/ICTer.2013.6761171
N. H. Nisansa Dilushan de Silva, Shahani Markus Weerawarana, and Amal Shehan Perera, "Enabling Effective Synoptic Assessment via Algorithmic Constitution of Review Panels", in Teaching, Assessment and Learning for Engineering (TALE), 2013 IEEE International Conference on, 08. 2013, pp. 776--781. doi: 10.1109/TALE.2013.6654543
N. H. N. D. de Silva, C. S. N. J. Fernando, M. K. D. T. Maldeniya, D. N. C. Wijeratne, A. S. Perera, and B Goertzel, "SeMap-Mapping Dependency Relationships into Semantic Frame Relationships", in Proceedings of the Engineering Research Unit Symposium, 12. 2011.
Workshop Papers
Ovindu Atukorala, Randeepa Appuhami, and Nisansa de Silva, "LawChain: A Resource-Efficient Blueprint for Legal Information Retrieval in Low-Resource Jurisdictions", in ICML 2026 GlobalSouthML, 2026.
Vishal Thenuwara, W M Yomal De Mel, and Nisansa De Silva, "Team VYN at SemEval-2026 Task 3: Dimensional Aspect-Based Sentiment Analysis", in Proceedings of the 20th International Workshop on Semantic Evaluation (2026), 2026, pp. 1755--1764. doi: 10.18653/v1/2026.semeval-1.223
Jayanath Senevirathna, Ayesh Vininda, Prasad Sandaruwan, Ridwan Shariffdeen, Sandareka Wickramanayake, and Nisansa de Silva, "FusionRepair: Iterative Multi-Line APR via Fusion", in IEEE/ACM International Workshop on Automated Program Repair (APR), 2025, pp. 27--34. doi: 10.1109/APR66717.2025.00009
Nethum Lamahewage, Nimantha Cooray, Ridwan Shariffdeen, Sandareka Wickramanayake, and Nisansa de Silva, "SCHOLIA-An XAI Framework for APR", in IEEE/ACM International Workshop on Automated Program Repair (APR), 2025, pp. 19--26. doi: 10.1109/APR66717.2025.00008
Nisansa de Silva, "Sinhala Diachronic Corpus", in NeurIPS 2025 AI for Science Workshop, 2025.
Menan Velayuthan, Nisansa De Silva, and Surangika Ranathunga, "Encoder-Aware Sequence-Level Knowledge Distillation for Low-Resource Neural Machine Translation", in Proceedings of the Eighth Workshop on Technologies for Machine Translation of Low-Resource Languages (LoResMT 2025), 2025, pp. 161--170.
Dineth Jayakody, Koshila Isuranda, A V A Malkith, Nisansa de Silva, G G N Sandamali, K L K Sudheera, and Sachintha Rajith, "Instruct-DeBERTa: A Hybrid Approach for Enhanced Aspect-Based Sentiment Analysis with Category Extraction", in Eighth Widening NLP Workshop (WiNLP 2024) Phase II, 2024.
Menan Velayuthan, Dilith Jayakody, Nisansa de Silva, Aloka Fernando, and Surangika Ranathunga, "Back to the Stats: Rescuing Low Resource Neural Machine Translation with Statistical Methods", in Proceedings of the Ninth Conference on Machine Translation, 2024, pp. 901--907. doi: 10.18653/v1/2024.wmt-1.87
Gathika Ratnayaka, Thejan Rupasinghe, Nisansa de Silva, Viraj Gamage, Menuka Warushavithana, and Amal Shehan Perera, "Shift-of-Perspective Identification Within Legal Cases", in Proceedings of the 3rd Workshop on Automated Detection, Extraction and Analysis of Semantic Information in Legal Texts, 2019.
Viraj Gamage, Menuka Warushavithana, Nisansa de Silva, Amal Shehan Perera, Gathika Ratnayaka, and Thejan Rupasinghe, "Fast Approach to Build an Automatic Sentiment Annotator for Legal Domain using Transfer Learning", in Proceedings of the 9th workshop on computational approaches to subjectivity, sentiment and social media analysis, 2018, pp. 260-265. doi: 10.18653/v1/W18-6238
Extended Abstracts
H L S Sankaja, R P G Sandeeptha, R M R U Ranasingha, S Wickramanayake, and Nisansa de Silva, "Generating Natural Language Explanations for Automated Program Repair Generated Patches", in International Conference of Sabaragamuwa University of Sri Lanka, 2025, pp. 61.
Niduni Kasige, Nishan Kavinda, Kisara Kodithuwakku, and Nisansa de Silva, "Hybrid Approach for Information Retrieval in Sri Lankan Legal Domain", in Proceedings of the Engineering Research Unit Symposium, 2025, pp. 70-71. doi: 10.31705/ERU.2025.33
Kushan Hewapathirana, Nisansa de Silva, and C. D. Athuraliya, "Adapter-based Fine-tuning for PRIMERA", in Applied Data Science \& Artificial Intelligence Symposium, 04. 2025. doi: 10.31705/ADScAI.2025.57
Akila Peiris and Nisansa de Silva, "A Primer on Synthesis and Evaluation of a Domain-specific Large Data Set for Dungeons \& Dragons", in 6th Widening NLP Workshop, 2022.
N. H. N. D. de Silva, S. M. Weerawarana, and A. S. Perera, "Automating the Composition and Scheduling Process for Synoptic Assessment Panels", in 9th SDC-SLAIHEE Higher Education Conference 2013, 06. 2013.
White Papers
Yudhanjaya Wijeratne and Nisansa de Silva, "Sinhala Language Corpora and Stopwords from a Decade of Sri Lankan Facebook", arXiv preprint arXiv:2007.07884, 2020. doi: 10.2139/ssrn.3650976
Yudhanjaya Wijeratne, Nisansa de Silva, and Yashothara Shanmugarajah, "Natural Language Processing for Government: Problems and Potential", LIRNEasia, 2019. doi: 10.13140/RG.2.2.34297.31845
Preprints
Mineth Weerasinghe, Himindu Kularathne, Methmini Madhushika, Danuka Lakshan, Nisansa de Silva, Adeesha Wijayasiri, and Srinath Perera, "TripleBound: Triplet-Guided Heterogeneous Graph Learning for Microservice Decomposition", arXiv preprint arXiv:2609.11212, 2026
Nevidu Jayatilleke and Nisansa de Silva, "Dynamics of meaning: Towards the Evaluation of Diachronic Semantic Change in Sinhala", arXiv preprint arXiv:2609.08609, 2026
Surangika Ranathunga, Nisansa de Silva, Aloka Fernando, Kavindu Warnakulasuriya, Isuru Wijesiri, Menan Velayuthan, Charitha Rathnayaka, Thivaharan Varatharajan, Sajeevi Silva, Piumi Kandanaarachchi, and Uthayasanker Thayasivam, "EnSiTa-A Trilingual Multi-Domain Parallel Dataset and Benchmark for Domain-Specific Machine Translation", ResearchGate, 2026
Thisen Ekanayake and Nisansa de Silva, "HelaBERT: Enhancing Sinhala Language Understanding with Dual Pooling Classification Head", arXiv preprint arXiv:2608.22922, 2026
Theekshana Samaradiwakara, Nisansa de Silva, and George C Lobb, "Semantics of Subterfuge: Benchmarking Legal Deception Detection Against General-domain State-of-the-Art", arXiv preprint arXiv:2607.29066, 2026
Nethmi Muthugala, Supryadi, Surangika Ranathunga, Nisansa de Silva, Ruijie Tao, Ovindu Gunatunga, Pengyun Zhu, Shaowei Zhang, Jingting Zheng, and Deyi Xiong, "LKValues: Aligning Large Language Models with Sri Lankan Societal Values", arXiv preprint arXiv:2607.20410, 2026
Nisansa de Silva and Surangika Ranathunga, "Sinhala Physical Common Sense Reasoning Dataset for Global PIQA", arXiv preprint arXiv:2602.02207, 2026. doi: 10.48550/arXiv.2602.02207
Nisansa de Silva, "Survey on Publicly Available Sinhala Natural Language Processing Tools and Research", arXiv preprint arXiv:1906.02358, 2019. doi: 10.48550/arXiv.1906.02358
Pengwei Wang, Dejing Dou, Fangzhao Wu, Nisansa de Silva, and Lianwen Jin, "Logic Rules Powered Knowledge Graph Embedding", arXiv preprint arXiv:1903.03772, 2019. doi: 10.48550/arXiv.1903.03772
Nisansa de Silva, Danaja Maldeniya, and Chamilka Wijeratne, "Subject Specific Stream Classification Preprocessing Algorithm for Twitter Data Stream", arXiv preprint arXiv:1705.09995, 2017. doi: 10.48550/ARXIV.1705.09995
Nisansa de Silva, "Sinhala Text Classification: Observations from the Perspective of a Resource Poor Language", , 2015

 Active
PI: Nisansa de Silva
The AI for Education project explores how artificial intelligence and digital technologies can enhance teaching, learning, and educational management within the Sri Lankan context.
 Active
PI: Sandareka Wickramanayake
We propose to advance automated program repair by leveraging natural language processing techniques, iterative repair strategies, and explainable AI frameworks to enhance accuracy, robustness, and interpretability of repair systems.
 Active
PI: Nisansa de Silva
We propose to advance aspect-based sentiment analysis (ABSA) by developing enhanced models, datasets, and evaluation methods that improve the accuracy and applicability of sentiment classification across multiple domains.
 Closed
PI: Dejing Dou
We propose to advance biomedical natural language processing by combining ontology-based reasoning, semantic search, and embedding-driven methods to improve information extraction, representation, and consistency detection in biomedical texts.
 Active
PI: Surangika Ranathunga
The Common Sense Reasoning project focuses on advancing culturally grounded evaluation and knowledge representation for language-based artificial intelligence systems.
 Active
PI: Surangika Ranathunga
The Data Quality Estimation and Improvement project focuses on analysing, measuring, and enhancing the quality of datasets used in natural language processing, particularly for multilingual and low-resource language applications.
 Active
PI: Nisansa de Silva
The Foundational Data Science project investigates how systematic data acquisition, integration, analysis, modelling, and visualisation can be applied to real-world problems to generate reliable and actionable knowledge.
 Active
PI: Surangika Ranathunga
We propose to create a multi-domain Neural Machine Translation (NMT) System for Sinhala, Tamil, and English, the official languages of Sri Lanka.
 Active
PI: Nisansa de Silva
The Knowledge Representation project investigates methods for structuring, aligning, and reasoning over knowledge extracted from language, with particular emphasis on low-resource settings, domain-specific semantics, and intelligent information access.
 Active
PI: Nisansa de Silva
The LLM Multi-agent Systems project explores how large language models can be coordinated as interacting agents to perform complex reasoning, cooperation, and task execution in natural language environments.
 Active
PI: Nisansa de Silva
We propose to advance natural language processing for low-resource settings by leveraging data augmentation, transfer learning, and model adaptation techniques to overcome the scarcity of annotated data and linguistic resources.
 Active
PI: Nisansa de Silva
This project attempts to generate adventures, images, and encounters for Dungeons and Dragons, the world's most popular Table Top Role Playing Game.
 Closed
PI: Rohan Samarajiva
We propose to investigate the role of natural language processing in government by building methods, frameworks, and resources that enable data-driven policy-making while ensuring ethical, transparent, and inclusive outcomes.
 Closed
PI: Dejing Dou
We propose to advance methods for semantic oppositeness detection in natural language, focusing on embedding-based models and contextual representations to improve reasoning and error detection in text.
 Active
PI: Nisansa de Silva
This project delves into the synergy between Natural Language Processing (NLP) and the legal domain, presenting novel solutions to enduring challenges.
 Active
PI: Nisansa de Silva
This project aims to develop a comprehensive diachronic corpus for the Sinhala language, addressing the scarcity of historical linguistic resources for a language spoken by approximately 16 million people in Sri Lanka.
 Active
PI: Nisansa de Silva
We propose to build and analyze Sinhala language resources, datasets, and models to strengthen NLP research for this low-resource language, while connecting it to English and Tamil through bilingual lexicons, embeddings, and cross-lingual methods.
 Active
PI: Nisansa de Silva
We propose to advance social media text analysis by combining linguistic study, preprocessing, and deep learning models to better capture sentiment, structure, and meaning in informal, large-scale user-generated text.
 Active
PI: Nisansa de Silva
The proposed research is expected to break new ground by addressing the dual challenges of linguistic complexity and cultural awareness in Sinhala, a low-resource language largely overlooked in LLM research.
 Active
PI: Nisansa de Silva
We propose to advance automatic summarization and generation techniques, with a focus on aspect-aware methods that capture fine-grained information and sentiment within concise textual representations.