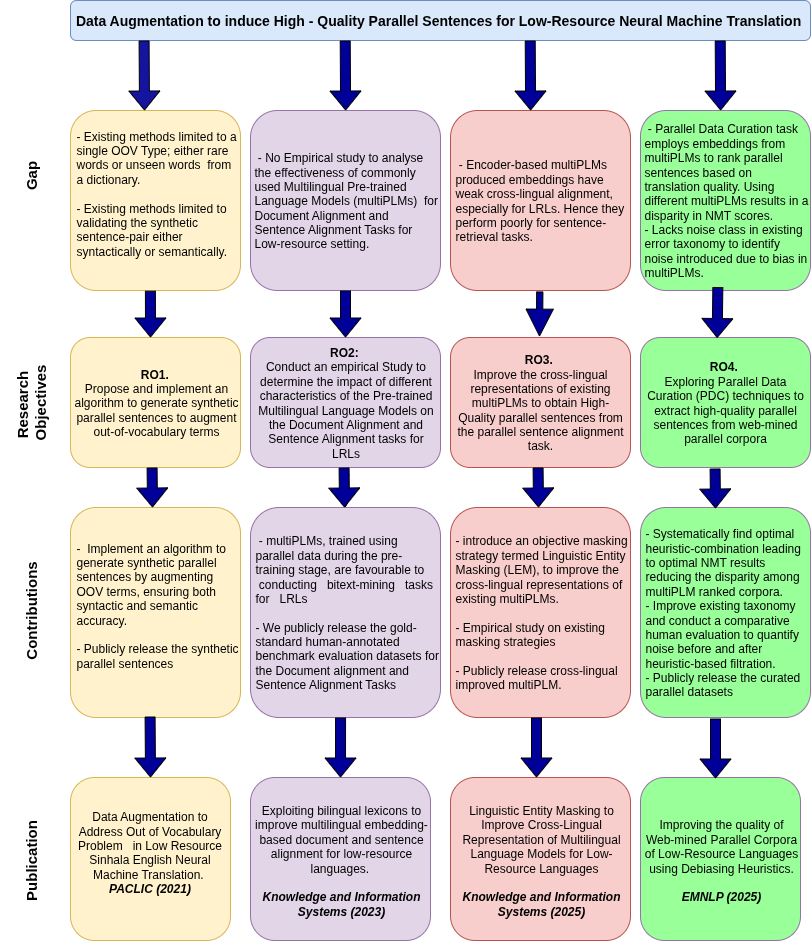
Supervised Neural Machine Translation (NMT) models rely on parallel data to produce reliable translations. A parallel dataset refers to a collection of texts in two or more languages in which each sentence in one language is aligned with its corresponding translation counterpart in the other language. NMT models have produced state-of-the-art results for High-Resource Languages. HRLs refer to languages that have linguistic resources and tool support. In Low-Resource settings, which means for languages with limited or no linguistic resources and/or tools, NMT performance is suboptimal due to two challenges: the parallel data scarcity problem and the presence of noise in the available parallel datasets. Data augmentation (DA) is a viable approach to address these problems, as it aims to induce high-quality parallel sentences efficiently using automatic means. In our research, we begin by analysing the limitations of the existing DA methods and propose strategies to overcome those limitations, aimed at improving the NMT performance. To generalise our findings, we conduct this study on three language pairs: English-Sinhala, English-Tamil and Sinhala-Tamil. They belong to three distinct language families. Further, Sinhala and Tamil are known to be morphologically rich languages, making NMT further challenging. First, we follow the word or phrase replacement-based augmentation strategy, where we induce synthetic parallel sentences by augmenting rare words and by using words from a bilingual dictionary. Our technique improves existing techniques by using both syntactic and semantic constraints to generate high-quality parallel sentences. This method improves translation quality for sequences containing out-of-vocabulary terms and yields better overall NMT scores than existing techniques. Secondly, we conduct an empirical study with three multilingual pre-trained language models (multiPLMs) and demonstrate that both the pre-training strategy and the nature of the pre-training data significantly affect the quality of mined parallel sentences. Thirdly, we enhance the cross-lingual sentence representations of existing encoder-based multiPLMs, in order to overcome their suboptimal performance in sentence retrieval tasks. We introduce Linguistic Entity Masking to enhance the cross-lingual representations of such multiPLMs and empirically prove that the improved representations lead to performance gains for cross-lingual tasks. Finally, we explore the Parallel Data Curation (PDC) task. In line with existing work, we identify that the scoring and ranking with different multiPLMs results in a disparity, which is caused by the multiPLMs' bias towards certain types of noisy parallel sentences. We show that multiPLM-based PDC, together with a heuristic combination, is capable of minimising this disparity while producing optimal NMT scores. Overall, we show that improving DA techniques leads to generating high-quality parallel data, which in turn leads to elevating the state-of-the-art benchmark NMT results further.
@phdthesis{fernando2025data,
  title={Data Augmentation to Induce High Quality Parallel Data for Low-Resource Neural Machine Translation},
  author={Fernando, W.A.S.A},
  year={2025},
  abstract={Supervised Neural Machine Translation (NMT) models rely on parallel data to produce reliable translations. A parallel dataset refers to a collection of texts in two or more languages in which each sentence in one language is aligned with its corresponding translation counterpart in the other language. NMT models have produced state-of-the-art results for High-Resource Languages. HRLs refer to languages that have linguistic resources and tool support. In Low-Resource settings, which means for languages with limited or no linguistic resources and/or tools, NMT performance is suboptimal due to two challenges: the parallel data scarcity problem and the presence of noise in the available parallel datasets. Data augmentation (DA) is a viable approach to address these problems, as it aims to induce high-quality parallel sentences efficiently using automatic means. In our research, we begin by analysing the limitations of the existing DA methods and propose strategies to overcome those limitations, aimed at improving the NMT performance. To generalise our findings, we conduct this study on three language pairs: English-Sinhala, English-Tamil and Sinhala-Tamil. They belong to three distinct language families. Further, Sinhala and Tamil are known to be morphologically rich languages, making NMT further challenging. First, we follow the word or phrase replacement-based augmentation strategy, where we induce synthetic parallel sentences by augmenting rare words and by using words from a bilingual dictionary. Our technique improves existing techniques by using both syntactic and semantic constraints to generate high-quality parallel sentences. This method improves translation quality for sequences containing out-of-vocabulary terms and yields better overall NMT scores than existing techniques. Secondly, we conduct an empirical study with three multilingual pre-trained language models (multiPLMs) and demonstrate that both the pre-training strategy and the nature of the pre-training data significantly affect the quality of mined parallel sentences. Thirdly, we enhance the cross-lingual sentence representations of existing encoder-based multiPLMs, in order to overcome their suboptimal performance in sentence retrieval tasks. We introduce Linguistic Entity Masking to enhance the cross-lingual representations of such multiPLMs and empirically prove that the improved representations lead to performance gains for cross-lingual tasks. Finally, we explore the Parallel Data Curation (PDC) task. In line with existing work, we identify that the scoring and ranking with different multiPLMs results in a disparity, which is caused by the multiPLMs' bias towards certain types of noisy parallel sentences. We show that multiPLM-based PDC, together with a heuristic combination, is capable of minimising this disparity while producing optimal NMT scores. Overall, we show that improving DA techniques leads to generating high-quality parallel data, which in turn leads to elevating the state-of-the-art benchmark NMT results further.},
  school={University of Moratuwa},
  misc={https://dl.lib.uom.lk/server/api/core/bitstreams/ddeb8ac3-cd95-4d9d-9366-1e741ea7ac70/content,NLP:ML,https://goo.gl/iY6aTr},
  url={https://dl.lib.uom.lk/server/api/core/bitstreams/ddeb8ac3-cd95-4d9d-9366-1e741ea7ac70/content}
}
Acknowledgement
This work was partially supported by the following grants:
2022
08
-
2025
12
Multi-domain Neural Machine Translation (NMT) System for Sinhala, Tamil, and English
$35,000 - Google/2022
We propose to create a multi-domain Neural Machine Translation (NMT) System for Sinhala, Tamil, and English, the official languages of Sri Lanka.


 Active


